Self-Hosted Whisper: Benchmarking Models for Meeting Notes
A self-hosted meeting-transcription pipeline on faster-whisper, benchmarking Whisper model sizes on a real 32-minute recording for accuracy vs speed.
Overview
A self-hosted meeting-transcription pipeline built on faster-whisper, with a benchmark comparing Whisper model sizes on a real 32-minute recording to find the accuracy/speed sweet spot for low-resource deployment.
I built a self-hosted pipeline that ingests meeting recordings (and notes/documents), transcribes audio locally with faster-whisper — a free, open-source reimplementation of OpenAI's Whisper model — and outputs clean Markdown for use as a knowledge base in NotebookLM. No per-minute API costs, no third-party transcription service, runs entirely on my own hardware.
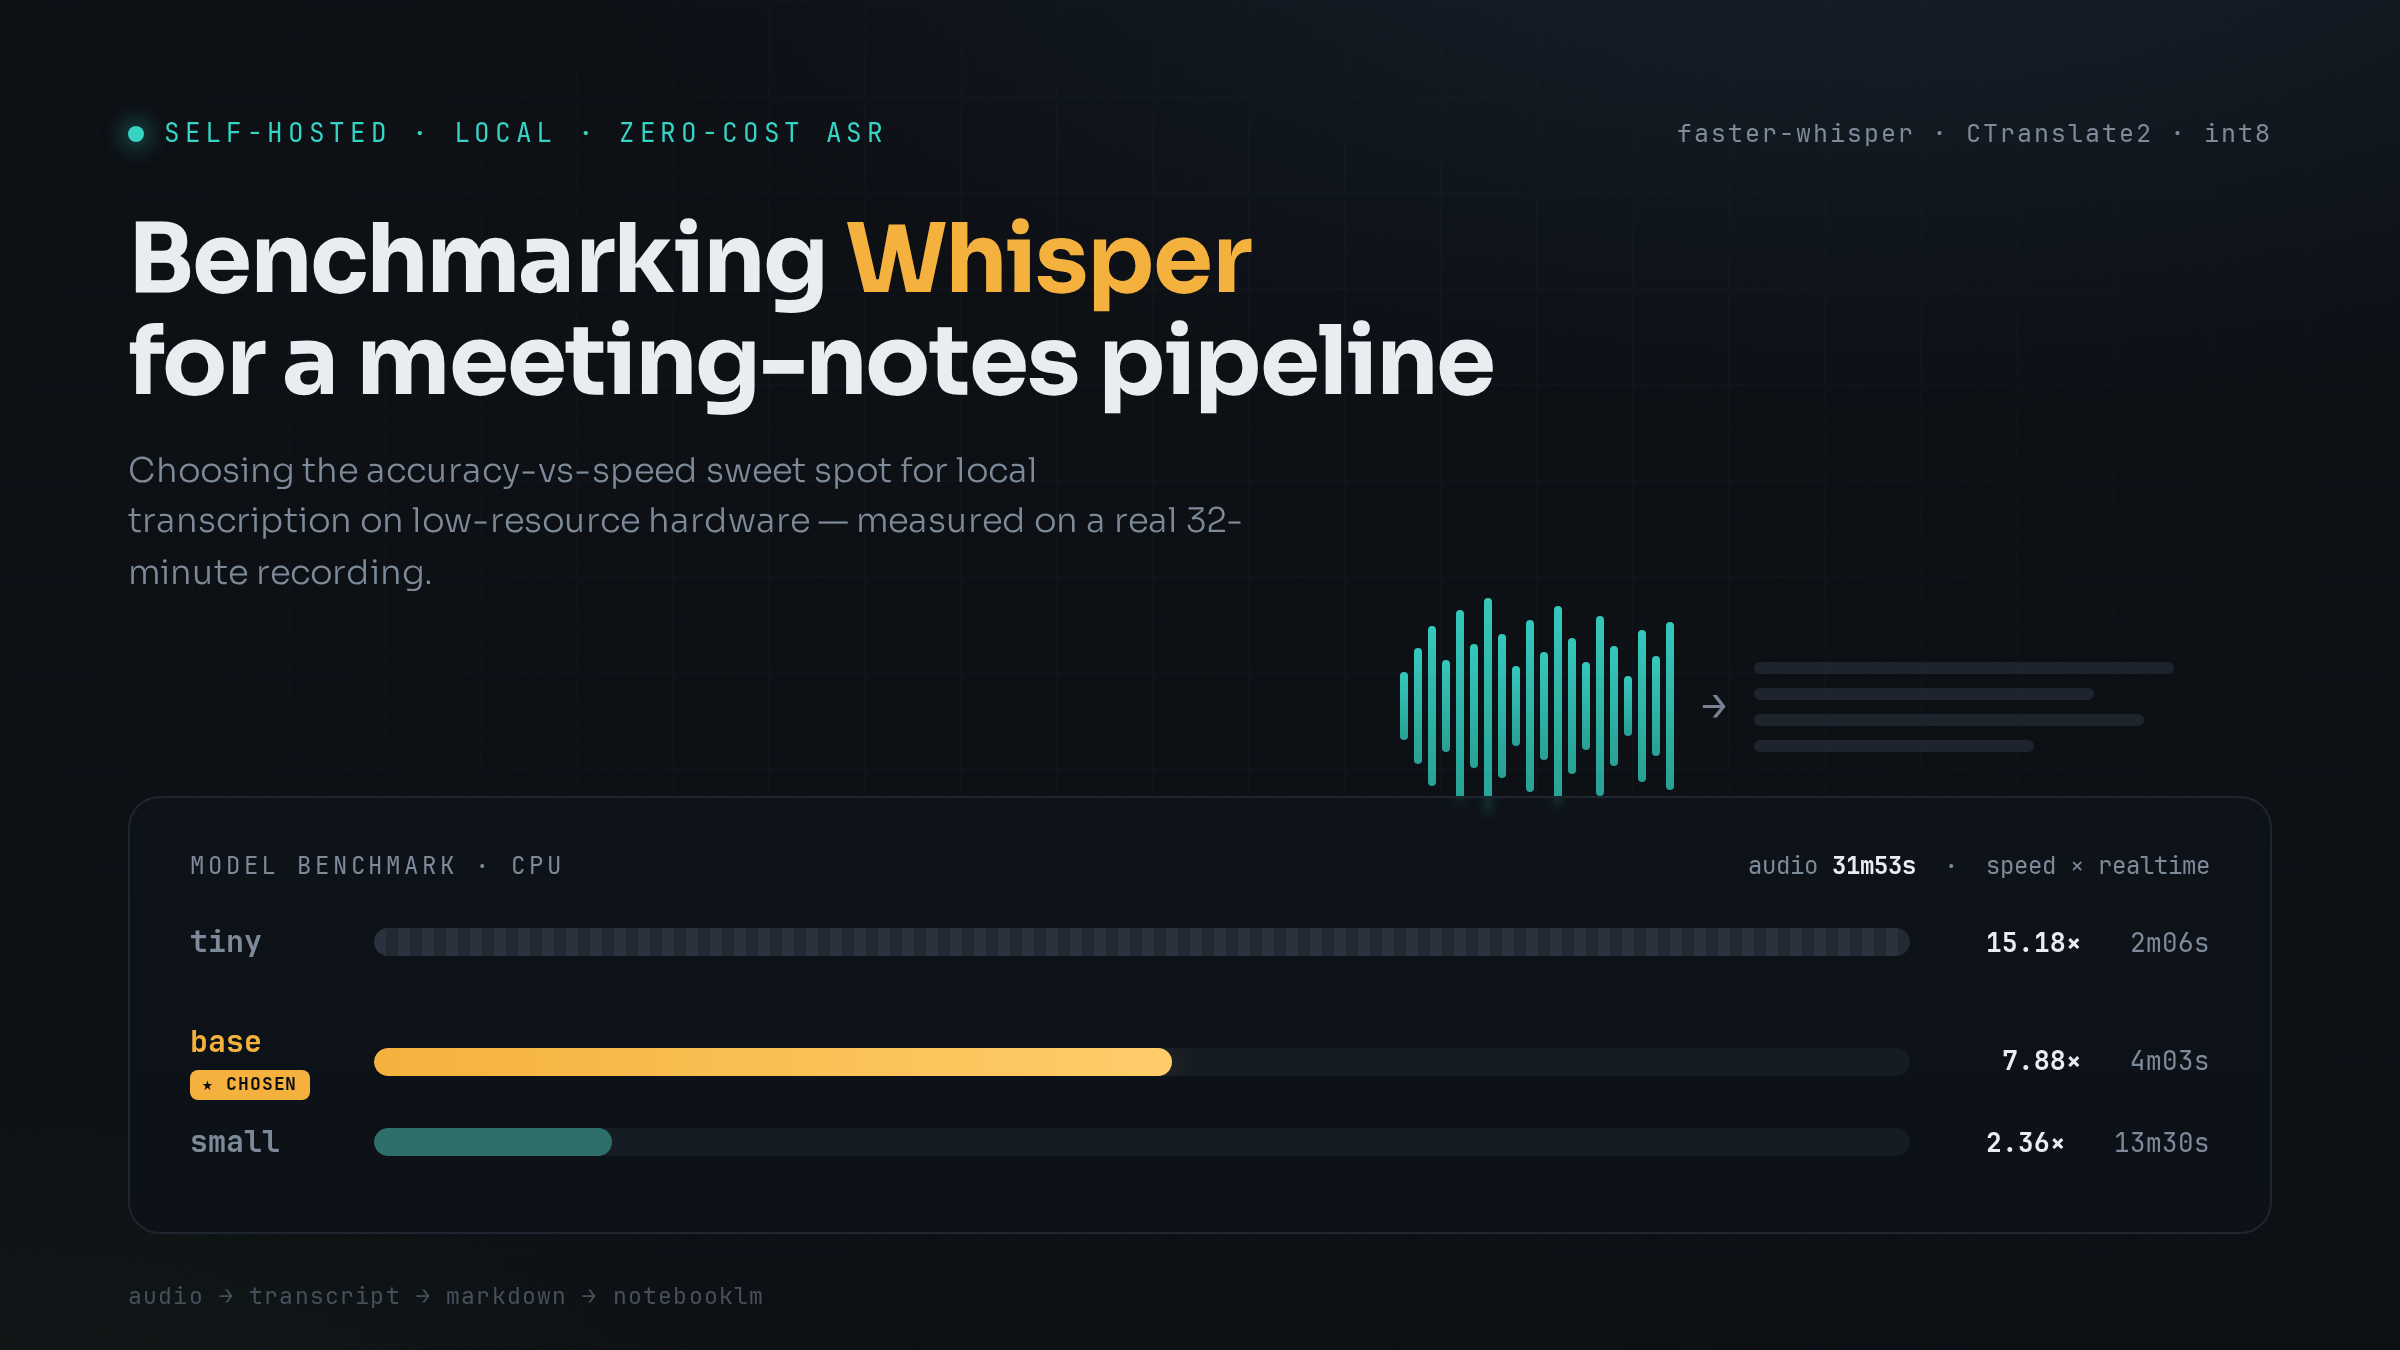
To choose the right model for a low-resource (2GB RAM) deployment target, I benchmarked three Whisper model sizes on a real 32-minute (1913s) recording, measuring transcription time, speed relative to realtime, and accuracy on technical vocabulary.
Tech Stack
- Language: Python 3.12
- Transcription:
faster-whisper(CTranslate2 runtime, int8 quantization), OpenAI Whisper models (tiny/base/small) - Media: FFmpeg (audio extraction from video)
- Document handling:
python-docx,pypdf - Sync/storage:
rclone(Google Drive bridge), Google Drive, NotebookLM - Deployment: systemd service on a Linux VPS
Benchmark Results
Audio length: 31m53s (1913s), CPU-bound.
| Model | Transcription Time | Speed vs. Realtime | Word Count |
|---|---|---|---|
| tiny | 2m06s | 15.18x | 5523 words |
| base | 4m03s | 7.88x | 5533 words |
| small | 13m30s | 2.36x | 5518 words |
Key Learnings & Conclusion
- Coverage wasn't the differentiator. Word counts were near-identical across all three models (~5520), so the difference isn't coverage — it's word-choice quality on technical terms.
tinywas fastest but unreliable. At 15x realtime it was the quickest, but it failed on exactly the words that matter: it invented non-words ("ganglinks" for "ganglion cells"), mangled drug and compound names ("magnesium 3 and 8" for "magnesium threonate"), and once dropped a "don't" that reversed a sentence's meaning.smallwas most accurate but slowest. At 2.36x realtime it had the best accuracy — and on a 2GB target it risks not fitting in memory at all.basewas the sweet spot. It captured essentially all ofsmall's important accuracy gains while running over 3x faster.
* ==**The Verdict:**== `base` is the optimal model for self-hosted meeting transcription on low-resource hardware — near-`small` accuracy at near-`tiny` convenience. Benchmark numbers are CPU-bound and hardware-specific, so the production target should be re-benchmarked on its own machine.